I am a PhD candidate in the Interpretable Neural Networks lab at Northeastern University, where I am fortunate to be advised by Prof. David Bau.
How do language models (or AI systems in general) perform complex reasoning tasks? Do they break down a complex problem into smaller steps, like a programmer implementing an algorithm? If so, how modular and composable are these small reasoning steps, and how are they implemented in the model’s internals? These are some of the key questions I am exploring in my research.
Broadly, I apply tools from mechanistic interpretability to form faithful abstractions of the inner workings of LLMs. I am interested in how such insights can help us address specific failure modes of AI systems by designing edits and interventions that target the right abstractions.
Before starting my PhD, I was a Software Engineer at Samsung Research and taught at SUST, where I completed my B.Sc. in Computer Science and Engineering.
Feel free to reach out if you would like to chat about research or collaboration, or if you have any questions about my work.
News
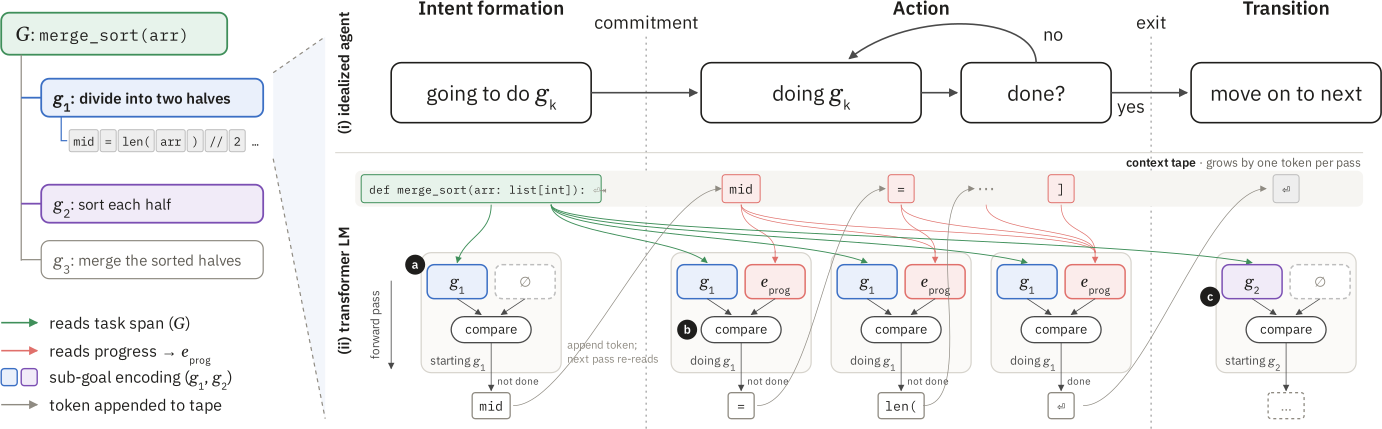
- New paper! Goal Encoding in LLMs. Do LLMs have goals? We find an explicit encoding of the LM's upcoming action in the outputs of a sparse set of attention heads, which we can read out in plain English before the model acts. We find that non-recurrent LMs sustain this goal encoding throughout the action by frequently re-reading and re-encoding the goal from the task-span in the prompt. Check out the project page and the interactive GoalScope demo.
- Recognized as a Gold Reviewer at ICML 2026.
- Two papers accepted at ICLR 2026: LLMs Process Lists With General Filter Heads and Language Models use Lookbacks to Track Beliefs! Also recognized as a Top-200 Reviewer.
- New paper! LLMs Process Lists With General Filter Heads. How do LMs filter a list of items? We find that LLMs use surprisingly elegant mechanisms, similar to the classic
filterfunction in programming languages. They implement the same filter operation with two mechanisms, depending on what information is available: (1) lazy evaluation: when the question comes after the list, the LM uses special attention heads; (2) eager evaluation: when the question comes before the list, the LM evaluates each item as it reads it and stores the result as a flag in the item’s representation. Check out the project page, or the thread for a quick summary. (Update: accepted at ICLR 2026!) - Serving as a reviewer for ICLR 2026.
- Attended the 2nd New England Mechanistic Interpretability (NEMI) workshop in Boston.
- Serving as a reviewer for NeurIPS 2026.
Older news
- Serving as a reviewer for COLM 2025.
- Attended NENLP 2025 at Yale.
- Serving as a reviewer for ICML 2025.
- The NNsight and NDIF paper is out! Super excited about NDIF’s mission to enable interpretability research on very large neural networks.
- Serving as a reviewer for ICLR 2025.
- Interpretability researchers are still trying to understand the right level of abstraction for conceptualizing neural network computations. Our new survey paper proposes a perspective grounded in causal mediation analysis.
- Serving as a reviewer for NeurIPS 2024. Excited to see many interesting works on interpretability, some of them building directly on work from our lab!
- Serving as a reviewer for COLM 2024.
- New paper, Locating and Editing Factual Associations in Mamba. Mamba is a new sequence-modeling architecture that matches the per-parameter performance of Transformers in multiple modalities, including language modeling. With such novel architectures, we interpretability researchers must ask: to what extent do our insights about a mechanism generalize across architectures? This paper is a case study: we apply the tools developed for understanding and editing factual associations in Transformers to Mamba, and check whether the insights carry over. Find more at the project page and code. (Update: accepted at COLM 2024!)
- Another paper! Function Vectors in Large Language Models. We show that LLMs encode functions (input-output mappings under a relation, or for a task such as translation) as vectors in their representations. Check out this thread for more. (Update: accepted at ICLR 2024!)
- New paper! Linearity of Relation Decoding in Transformer LMs. We show that for a subset of relations, the LLM’s (highly non-linear) relation decoding can be well approximated by a single linear transformation (LRE) on the subject representation after some intermediate layer, and that this LRE can be obtained from a first-order approximation of the LLM’s computation on a single input. Find more at the project page and code. (Update: accepted at ICLR 2024!)
- Our paper Mass-Editing Memory in a Transformer has been accepted at ICLR 2023 (top 25%)!
- New paper! Mass-Editing Memory in a Transformer. We scale up ROME to edit up to 10K memories in an LLM. Find more at the project page.
- Starting my PhD at Northeastern University, Boston, working with Prof. David Bau on the interpretability of LLMs.
Selected Publications
See Google Scholar for the complete list.


Experience
 Northeastern University Graduate TA, DS 4440: Practical Deep Networks
 Shahjalal University of Science and Technology Lecturer, Dept. of Computer Science and Engineering (profile)
 Samsung R&D Institute Bangladesh Software Engineer
Education
- Northeastern University PhD in Computer Science, Interpretable Neural Networks lab, advised by David Bau
- Northeastern University MS in Computer Science
- Shahjalal University of Science and Technology B.Sc. in Computer Science and Engineering